DisStance
News-title pairs annotated with a similarity score (0.0 to 1.0, step 0.1) and a stance label. One row is one pair, with every annotator's judgment.
 Dataset on Hugging Face
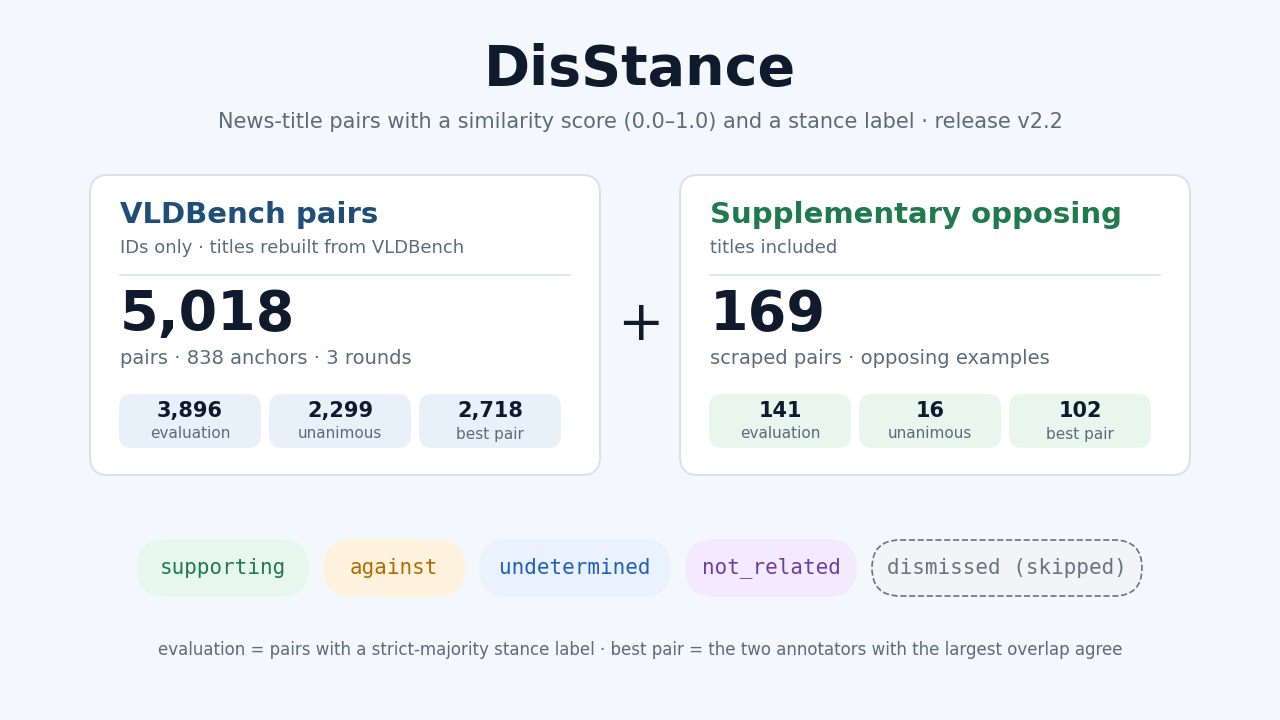
VLDBench pairs (IDs only) and supplementary opposing pairs (titles included), with their evaluation and agreement subsets.
VLDBench pairs
Supplementary opposing
Pick the right set
| Goal | Config | Rows |
|---|---|---|
| All VLDBench pairs, every annotator | vldbench | 5,018 |
| Evaluation set (strict-majority stance label) | vldbench_majority | 3,896 |
| All annotators agree | vldbench_unanimous | 2,299 |
| Best annotator pair agrees (C and E) | vldbench_best_pair | 2,718 |
| All supplementary pairs, with titles | supplementary_opposing | 169 |
| Supplementary evaluation set | supplementary_opposing_majority | 141 |
| Supplementary, full agreement | supplementary_opposing_unanimous | 16 |
| Supplementary, best pair agrees (B and F) | supplementary_opposing_best_pair | 102 |
| One row per judgment | *_annotations_long | 20,357 / 1,007 |
The reference label of a pair is majority_label: the stance chosen by more than half of its annotators, dismissed judgments excluded. Agreement and majority configs also give related and similarity_mean. The long tables are meant for agreement studies, not for training.
Labels
Access
The dataset card on Hugging Face is public. Downloads are gated: click Access repository on the dataset page, fill in the form and wait for manual approval, then log in with hf auth login.
Load
from datasets import load_dataset

REPO = "AI4Debunk/DisStance-Similarity-Dataset"
pairs = load_dataset(REPO, "vldbench", split="train", revision="v2.2")
evaluation = load_dataset(REPO, "vldbench_majority", split="train", revision="v2.2")
opposing = load_dataset(REPO, "supplementary_opposing_majority", split="train", revision="v2.2")
The VLDBench configs contain IDs only. extract_annotations.py in the code repository adds the VLDBench headlines and text:
python extract_annotations.py --config vldbench_majority --format csv --output vldbench_majority.csvHow to cite
Placeholder (update when the paper is public):
Mokhtari, M. E. A., et al. (2026). DisStance: A Dataset for Title-Level Similarity and Stance Relations in Disinformation Detection. Preprint forthcoming.
@misc{disstance2026,
  title        = {DisStance: A Dataset for Title-Level Similarity and Stance Relations in Disinformation Detection},
  author       = {Mokhtari, Mohammed El Amine and others},
  year         = {2026},
  howpublished = {Dataset},
  note         = {Citation placeholder, to be replaced with the paper entry},
  url          = {https://huggingface.co/datasets/AI4Debunk/DisStance-Similarity-Dataset}
}